Author: John Serra

  • The Machine is Wrong: Designing AI Feedback Loops for EFL

    The Machine is Wrong: Designing AI Feedback Loops for EFL

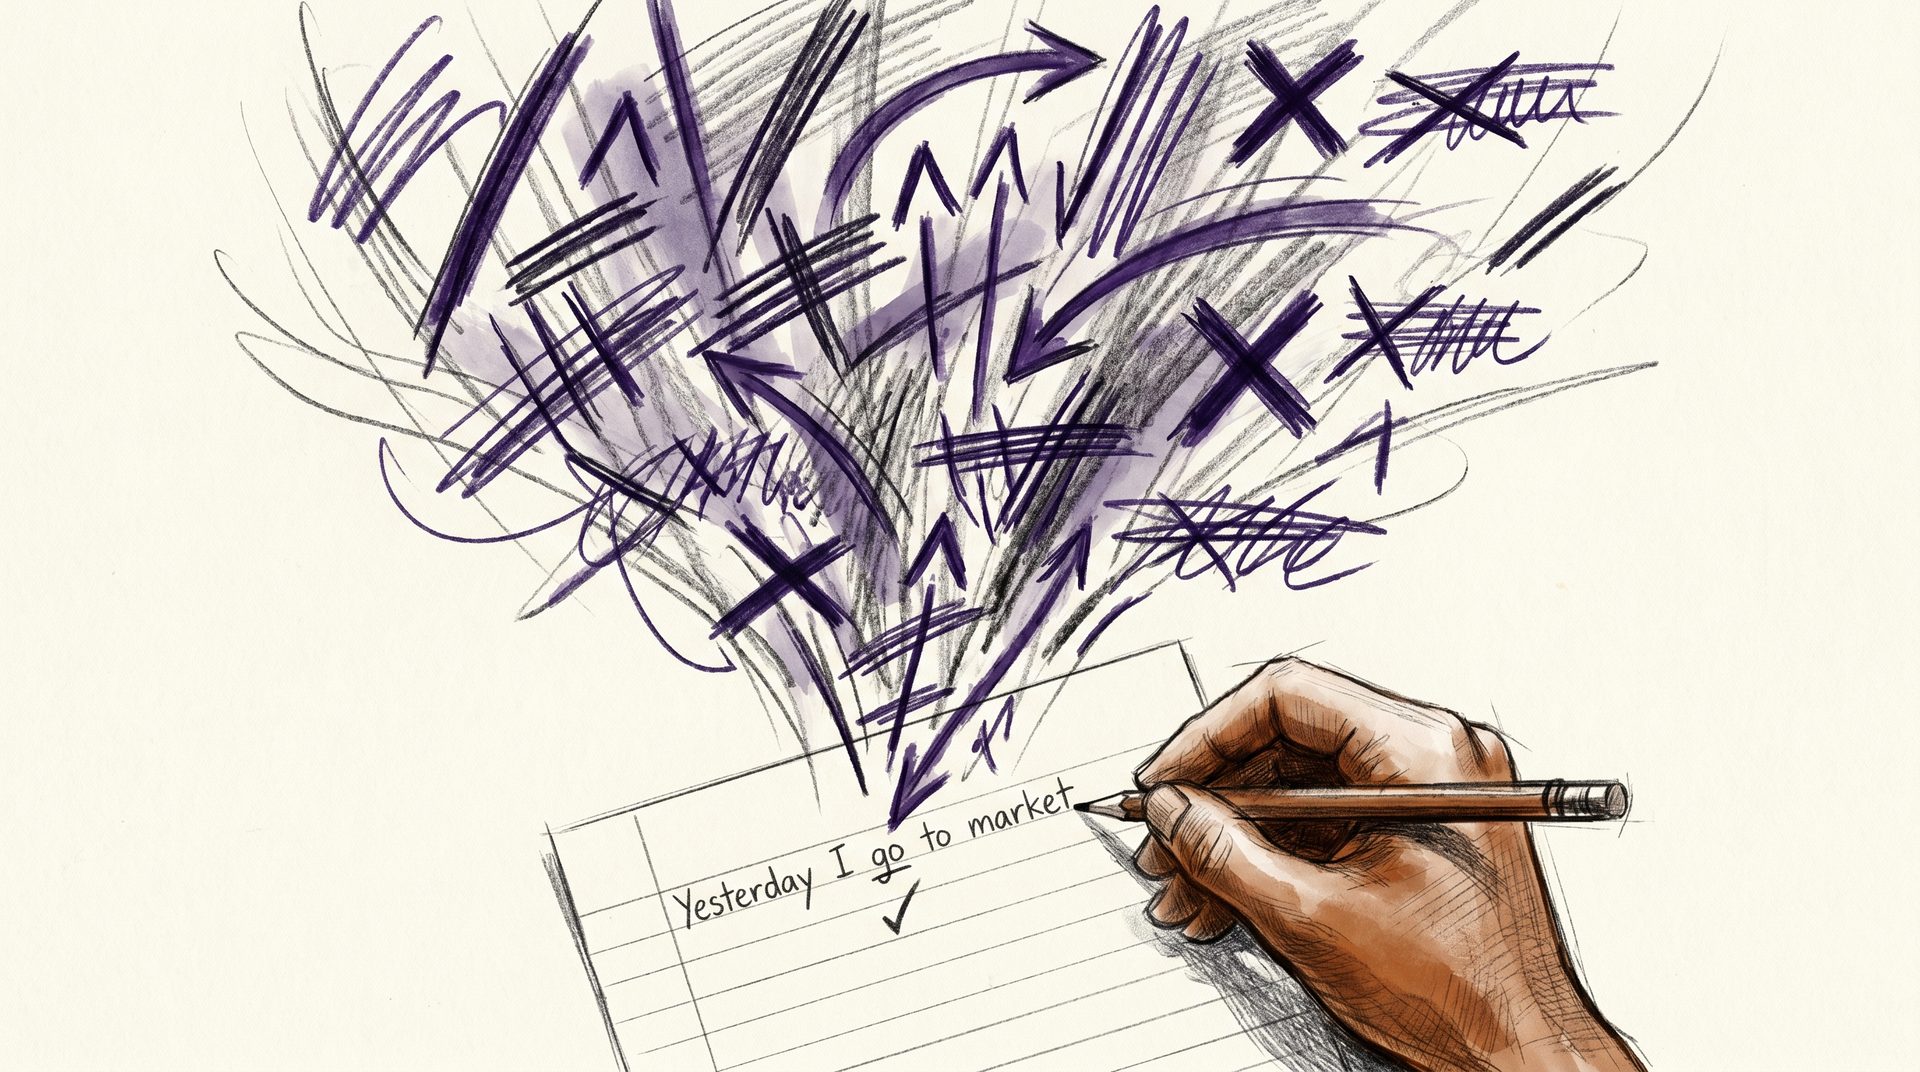
    I want to start with a moment that should be easy. Imagine an A1 learner — call her Ayşe, six weeks into her first Business English course — typing this into a practice box:

    Yesterday I go to market and I buy bread.

    A model might return:

    Yesterday, I went to the market and bought some bread.

    Fluent? Yes. Useful feedback? That depends on what Ayşe is practicing.

    For this example, suppose the teacher has introduced one small target: using went rather than go to describe yesterday. The exercise is a scaffolded practice turn, not a test of the entire past tense or article system. The rewrite changes the target verb, a second verb, the article before market, and the phrasing around bread. It supplies a finished sentence without asking Ayşe to practice the target herself.

    A response aligned with that narrow objective could be:

    You told me when it happened: yesterday. For yesterday, use went instead of go. Try that part again.

    That response does not certify the whole sentence as correct. It gives Ayşe one manageable next step. Other features can be addressed when they become the lesson target.

    This is what I mean by the machine is wrong: a response can be linguistically accurate and still miss the instructional purpose. For CareerTalkLab (CTL), in our English as a Foreign Language (EFL) section, the design challenge is to make that purpose explicit.

    Why it fails

    Frontier models can produce fluent rewrites and discuss language-learning frameworks. Neither ability guarantees that a particular feedback turn serves a particular learner. The failure mode has three layers.

    Insufficient learner context. Knowing about the Common European Framework of Reference for Languages (CEFR) or Pearson’s Global Scale of English (GSE) is different from knowing what Ayşe has actually been taught. A level label does not tell the tutor which vocabulary is familiar, which structure is being practiced, or what the previous attempt showed. The tutor needs the lesson target, relevant learning history, and a clear policy on what to correct.

    The level references need precision too. Pearson’s adult GSE grammar guide lists A1 as GSE 22–29. It places basic a/an objectives at A1 and broader article selection later. Articles are not simply a “B1 problem.” The practical question is whether this use has been introduced to this learner for this task.

    Insufficient first-language context. Turkish and English organize grammar differently, including article use and tense/aspect. Those differences can help a teacher anticipate possible first-language (L1) transfer. A model may know about such patterns, but reliable feedback requires applying that knowledge carefully to the learner’s actual error. A learner’s L1 is useful context, not a diagnosis: a single sentence does not establish why an error occurred.

    An unspecified correction policy. CTL’s beginner instruction draws on Applied Verbal Behavior and errorless teaching approaches, using prompts and scaffolds to support successful practice. Selective correction is one part of the policy for narrowly targeted exercises; it is not the whole definition of errorless teaching, or a universal rule for EFL.

    Broader corrective feedback can be useful in other settings. For example, research on an online EFL writing course found benefits from unfocused indirect feedback combined with additional practice tasks. That context differs from a beginner’s short practice turn. The correction policy should follow the learner, task, and objective.

    So the model’s fluency is not the problem by itself. The problem is fluency without a sufficiently specified teaching task.

    The loop

    The teacher owns the instructional decisions. The model can assist, but the surrounding system must carry the constraints and check whether they survive generation. Here is the design I want CTL’s feedback loop to follow.

    Constrain the tutor before generation. Give it the target structure, familiar language, relevant prior attempts, and examples of acceptable feedback. Include examples of what to leave for later. Worked examples make the intended behavior concrete; their benefit still needs to be tested against the same rubric as any other prompting choice.

    Evaluate the response before delivery. A separate judge can score feedback against a lesson-specific rubric: level appropriateness, target reinforcement, correction scope, and tone. A failed response can be regenerated with the failure reason supplied as context.

    But a second model is not an independent authority merely because it has a different role. It can share the tutor’s blind spots. The judge needs calibration against expert-reviewed examples, checks for missed failures and false alarms, and an option to mark a case uncertain. Anthropic’s evaluation guidance likewise recommends calibrating model graders with human experts.

    Retries need a limit. If the system cannot produce acceptable feedback within that limit, it should use a teacher-approved fallback or hold the turn for review rather than keep generating until something passes. Cost, latency, and incorrect approvals belong in the evaluation alongside the rubric score.

    Keep human review upstream. A human learner reviewed every lesson before soft launch. Lesson design is where mistakes can compound: an unclear objective or a poorly chosen scaffold can shape many subsequent feedback turns. Reviewing the lesson first reduces the burden on the runtime judge.

    Let the learner challenge the feedback. A low-friction “this correction was off” signal can expose problems our test set missed. The learner is the authority on confusion and frustration, but the flag alone does not establish that the language correction was wrong.

    The loop should be flag → expert review → expected response → regression test. Reviewers need enough lesson and conversation context to distinguish an incorrect correction from an unclear explanation, a level mismatch, or a valid correction the learner has not understood. Confirmed cases can become tests of the behavior we want to preserve. A raw flag is a candidate failure case, not automatically a labeled training example.

    The pattern is constrained generation, evaluated generation, observed generation. For CTL’s learner-facing feedback, I want all three.

    The broader lesson

    The temptation when building with frontier models is to treat general capability as proof of domain suitability. A fluent answer is only one dimension of success. In teaching, we also care about what the learner notices, practices, and can later do without assistance.

    For builders in expert domains, the lesson is the same: the model is not the product. The product includes the task definition, constraints, review process, and evidence that the whole system performs its intended job.

    Domain experts should define those objectives and validate the examples. Models can help propose rules and draft rubrics, but their proposals still need review. Delegating generation does not remove responsibility for instructional decisions.

    What this means for the CTL roadmap

    These were the design priorities heading into beta in May 2026. They describe the intended release policy, not measured evidence that the complete loop has already met it.

    The eval suite belongs on the critical path. Before expanding into B1+ lessons, define an acceptable level-mismatch rate, assemble an expert-reviewed test set, and check performance by learner level and lesson target. A high aggregate pass rate should not hide a weak category.

    Learner feedback belongs in the core workflow too. Collecting flags is only the start; the review process must turn confirmed problems into actionable examples and regression tests.

    The initial beta focus is Turkish A1/A2 learners. Keeping the cohort narrow makes it easier to examine whether the feedback matches those learners’ tasks and needs before broadening the audience. It is a scope decision, not a claim that L1 transfer is necessarily strongest at those levels.

    The IELTS track should remain gated until the Executive track’s feedback quality is stable against agreed criteria. One track at a time, with empirical testing guiding expansion.

    To show whether this design works, we need to report more than judge scores: expert-confirmed failure rates, disagreement between experts and the judge, feedback latency, and evidence that learners can use the target in a later attempt. Those are the results a follow-up should examine.

    The machine can be right about English and wrong about the next teaching move. Trust has to be earned on each instructional task. That is the design principle for CTL.
  • Makine Yanılıyor: EFL İçin Yapay Zekâ Geri Bildirim Döngüleri Tasarlamak

    Makine Yanılıyor: EFL İçin Yapay Zekâ Geri Bildirim Döngüleri Tasarlamak

    Kolay olması gereken bir anla başlamak istiyorum. A1 seviyesindeki bir öğrenci düşünün: Adına Ayşe diyelim; ilk İş İngilizcesi kursunun altıncı haftasında, alıştırma kutusuna şunu yazıyor:

    Yesterday I go to market and I buy bread.

    Bir model şu yanıtı verebilir:

    Yesterday, I went to the market and bought some bread.

    Akıcı mı? Evet. Yararlı bir geri bildirim mi? Bu, Ayşe’nin neyi çalıştığına bağlı.

    Bu örnekte öğretmenin tek, küçük bir hedef belirlediğini varsayalım: Dünü anlatırken go yerine went kullanmak. Alıştırma, desteklerle yapılandırılmış bir pratik adımı; geçmiş zamanın ya da artikel sisteminin tamamını sınayan bir test değil. Yeniden yazılan cümle hedef fiili, ikinci bir fiili, market sözcüğünün önündeki artikeli ve bread çevresindeki ifadeyi değiştiriyor. Ayşe’den hedef yapıyı kendisinin uygulamasını istemeden, tamamlanmış bir cümle sunuyor.

    Bu dar kapsamlı hedefle uyumlu bir yanıt şöyle olabilir:

    You told me when it happened: yesterday. For yesterday, use went instead of go. Try that part again.

    Bu yanıt, cümlenin tamamının doğru olduğunu onaylamıyor. Ayşe’ye atabileceği, yönetilebilir tek bir sonraki adım veriyor. Diğer unsurlar, dersin hedefi olduklarında ele alınabilir.

    Makine yanılıyor derken kastettiğim bu: Bir yanıt dil açısından doğru olabilir, ama yine de öğretim amacını karşılamayabilir. CareerTalkLab’in (CTL) yabancı dil olarak İngilizce (English as a Foreign Language, EFL) bölümünde tasarımın zorluğu, bu amacı açıkça tanımlamak.

    Neden Başarısız Oluyor?

    En gelişmiş modeller akıcı yeniden yazımlar üretebilir ve dil öğrenme çerçevelerini tartışabilir. Bu yeteneklerin hiçbiri, belirli bir geri bildirimin belirli bir öğrenciye yararlı olacağını garanti etmez. Başarısızlığın üç katmanı var.

    Öğrenciye ilişkin bağlamın yetersizliği. Diller İçin Avrupa Ortak Başvuru Metni’ni (CEFR) veya Pearson’ın Küresel İngilizce Ölçeği’ni (Global Scale of English, GSE) bilmek, Ayşe’ye gerçekte ne öğretildiğini bilmekten farklıdır. Bir seviye etiketi, eğitmene hangi sözcüklerin tanıdık olduğunu, hangi yapının çalışıldığını veya önceki denemenin ne gösterdiğini söylemez. Eğitmenin dersin hedefini, ilgili öğrenme geçmişini ve nelerin düzeltileceğine ilişkin açık bir politikayı bilmesi gerekir.

    Seviye referanslarında da kesinlik gerekir. Pearson’ın yetişkinler için GSE dilbilgisi rehberi, A1’i GSE 22–29 aralığında gösteriyor. Temel a/an hedeflerini A1’e, daha kapsamlı artikel seçimini ise daha sonraki seviyelere yerleştiriyor. Artikeller yalnızca bir “B1 meselesi” değildir. Pratikte sorulması gereken, bu kullanımın bu öğrenciye bu görev için öğretilip öğretilmediğidir.

    Ana dile ilişkin bağlamın yetersizliği. Türkçe ve İngilizce; artikel kullanımı, zaman ve görünüş dahil olmak üzere dilbilgisini farklı biçimlerde düzenler. Bu farklılıklar, öğretmenin olası ana dil (L1) aktarımını öngörmesine yardımcı olabilir. Bir model bu tür örüntüleri biliyor olabilir; ancak güvenilir geri bildirim, bu bilgiyi öğrencinin gerçek hatasına dikkatle uygulamayı gerektirir. Öğrencinin ana dili yararlı bir bağlamdır, bir tanı değildir: Tek bir cümle, hatanın neden oluştuğunu ortaya koymaz.

    Düzeltme politikasının tanımlanmaması. CTL’nin başlangıç seviyesi öğretimi, Uygulamalı Sözel Davranış ve hatasız öğretim yaklaşımlarından yararlanır; başarılı pratiği desteklemek için ipuçları ve kademeli destekler kullanır. Seçici düzeltme, dar kapsamlı hedeflere yönelik alıştırmalarda uygulanan politikanın bir parçasıdır; hatasız öğretimin bütün tanımı veya EFL için evrensel bir kural değildir.

    Daha geniş kapsamlı düzeltici geri bildirim, başka ortamlarda yararlı olabilir. Örneğin, çevrim içi bir EFL yazma dersi üzerine yapılan araştırma, tek bir hata türüyle sınırlanmayan dolaylı geri bildirimin ek alıştırmalarla birlikte yarar sağladığını buldu. Bu bağlam, başlangıç seviyesindeki bir öğrencinin kısa pratik adımından farklıdır. Düzeltme politikası öğrenciye, göreve ve hedefe göre belirlenmelidir.

    Dolayısıyla modelin akıcılığı tek başına sorun değil. Sorun, yeterince tanımlanmamış bir öğretim görevindeki akıcılık.

    Geri Bildirim Döngüsü

    Öğretim kararlarının sorumluluğu öğretmendedir. Model yardımcı olabilir; ancak onu çevreleyen sistem, kısıtları taşımalı ve yanıt üretilirken bunların korunup korunmadığını kontrol etmelidir. CTL’nin geri bildirim döngüsünün izlemesini istediğim tasarım şöyle.

    Yanıt üretiminden önce eğitmeni sınırlandırın. Hedef yapıyı, öğrencinin bildiği dili, ilgili önceki denemeleri ve kabul edilebilir geri bildirim örneklerini verin. Daha sonraya bırakılması gereken unsurlara ilişkin örnekler de ekleyin. Açıklamalı örnekler, istenen davranışı somutlaştırır; ancak yararları, diğer tüm talimatlandırma tercihleri gibi aynı değerlendirme ölçütleriyle sınanmalıdır.

    Yanıtı öğrenciye sunmadan önce değerlendirin. Ayrı bir değerlendirici, geri bildirimi derse özgü bir rubriğe göre puanlayabilir: seviyeye uygunluk, hedefi pekiştirme, düzeltme kapsamı ve üslup. Başarısız bir yanıt, başarısızlık gerekçesi bağlam olarak verilerek yeniden üretilebilir.

    Ancak ikinci bir model, yalnızca farklı bir rolü olduğu için bağımsız bir otorite sayılmaz. Eğitmenle aynı kör noktalara sahip olabilir. Değerlendiricinin uzmanlarca incelenmiş örneklerle kalibre edilmesi, kaçırılan hatalar ve yanlış alarmlar açısından kontrol edilmesi ve bir durumu belirsiz olarak işaretleyebilmesi gerekir. Anthropic’in değerlendirme rehberi de model tabanlı değerlendiricilerin insan uzmanlarla kalibre edilmesini öneriyor.

    Yeniden denemelerin bir sınırı olmalı. Sistem bu sınır içinde kabul edilebilir geri bildirim üretemiyorsa, bir yanıt kontrolden geçene kadar üretmeye devam etmek yerine öğretmen tarafından onaylanmış bir yedek yanıt kullanmalı veya o adımı inceleme için bekletmelidir. Değerlendirmede rubrik puanının yanında maliyet, gecikme ve hatalı onaylar da yer almalıdır.

    İnsan incelemesini sürecin başında tutun. Sınırlı kullanıma açılmadan önce, gerçek bir öğrenci her dersi gözden geçirdi. Hataların birikerek büyüyebildiği yer ders tasarımıdır: Belirsiz bir hedef veya kötü seçilmiş bir destek, sonraki birçok geri bildirimi şekillendirebilir. Önce dersi incelemek, kullanım sırasında çalışan değerlendiricinin yükünü azaltır.

    Öğrencinin geri bildirime itiraz edebilmesini sağlayın. Kolayca iletilebilen bir “bu düzeltme isabetsizdi” bildirimi, test kümemizin kaçırdığı sorunları ortaya çıkarabilir. Kafa karışıklığı ve hayal kırıklığı konusunda söz sahibi öğrencidir; ancak bildirim tek başına dil düzeltmesinin yanlış olduğunu kanıtlamaz.

    Döngü bildirim → uzman incelemesi → beklenen yanıt → regresyon testi şeklinde olmalı. İncelemeyi yapanların; yanlış bir düzeltmeyi belirsiz bir açıklamadan, seviye uyumsuzluğundan veya öğrencinin anlamadığı geçerli bir düzeltmeden ayırabilmesi için yeterli ders ve konuşma bağlamına ihtiyacı vardır. Doğrulanmış durumlar, korumak istediğimiz davranışı sınayan testlere dönüşebilir. Ham bir bildirim, olası bir başarısızlık örneğidir; otomatik olarak etiketlenmiş bir eğitim örneği değildir.

    Bu yaklaşım kısıtlanmış üretim, değerlendirilmiş üretim, gözlemlenen üretim olarak özetlenebilir. CTL’nin öğrenciye sunduğu geri bildirimde üçünü de istiyorum.

    Daha Genel Ders

    En gelişmiş modellerle ürün geliştirirken, genel yeteneği belirli bir alana uygunluğun kanıtı saymak cazip gelebilir. Akıcı bir yanıt, başarının yalnızca bir boyutudur. Öğretimde, öğrencinin neyi fark ettiğini, neyi uyguladığını ve daha sonra yardım almadan ne yapabildiğini de önemseriz.

    Uzmanlık gerektiren alanlarda ürün geliştirenler için ders aynı: model, ürünün kendisi değildir. Ürün; görev tanımını, kısıtları, inceleme sürecini ve bütün sistemin amaçlanan işi yaptığını gösteren kanıtları içerir.

    Bu hedefleri alan uzmanları tanımlamalı ve örneklerin geçerliliğini doğrulamalıdır. Modeller kural önermeye ve değerlendirme rubrikleri hazırlamaya yardımcı olabilir; ancak önerileri yine de incelenmelidir. Üretimi devretmek, öğretim kararlarının sorumluluğunu ortadan kaldırmaz.

    Bunun CTL Yol Haritası İçin Anlamı

    Mayıs 2026’da beta aşamasına girerken tasarım öncelikleri bunlardı. Bunlar, planlanan yayına alma politikasını anlatıyor; döngünün tamamının bu koşulları şimdiden karşıladığını gösteren ölçülmüş kanıtlar değil.

    Değerlendirme testleri kritik yol üzerinde yer almalı. B1 ve üzeri derslere geçmeden önce kabul edilebilir bir seviye uyumsuzluğu oranı tanımlayın, uzmanlarca incelenmiş bir test kümesi oluşturun ve performansı öğrenci seviyesine ve ders hedefine göre kontrol edin. Toplamda yüksek bir başarı oranı, zayıf bir kategoriyi gizlememeli.

    Öğrenci geri bildirimi de temel iş akışının parçası olmalı. Bildirimleri toplamak yalnızca başlangıçtır; inceleme süreci, doğrulanmış sorunları kullanılabilir örneklere ve regresyon testlerine dönüştürmelidir.

    İlk beta aşamasının odağı, ana dili Türkçe olan A1/A2 öğrencileri. Grubu dar tutmak, daha geniş bir kitleye açılmadan önce geri bildirimin bu öğrencilerin görevlerine ve ihtiyaçlarına uyup uymadığını incelemeyi kolaylaştırır. Bu bir kapsam kararıdır; ana dil aktarımının mutlaka bu seviyelerde en güçlü olduğu iddiası değildir.

    Executive programının geri bildirim kalitesi, üzerinde uzlaşılan ölçütlere göre istikrarlı hale gelene kadar IELTS programı açılmamalıdır. Her seferinde tek bir program; genişlemeye deneysel testler yön vermeli.

    Bu tasarımın işe yarayıp yaramadığını göstermek için değerlendirici puanlarından fazlasını raporlamamız gerekir: uzmanlarca doğrulanmış başarısızlık oranları, uzmanlarla değerlendirici arasındaki görüş ayrılıkları, geri bildirim gecikmesi ve öğrencilerin hedef yapıyı sonraki bir denemede kullanabildiğine ilişkin kanıtlar. Bir sonraki yazı bu sonuçları incelemeli.

    Makine İngilizce konusunda haklı, öğretimde atılacak bir sonraki adım konusunda ise haksız olabilir. Her öğretim görevinde güveni hak etmek gerekir. CTL’nin tasarım ilkesi bu.

  • Mimarın Atılımı: Çok Kanallı Bir Dünyada Eylem Gücünü Yönetmek

    Mimarın Atılımı: Çok Kanallı Bir Dünyada Eylem Gücünü Yönetmek

    Çok Kanallı Sürtünme

    Mevcut görevimde günlük gerçekliğim şu şekilde ilerliyor: Sabahları bir kentsel mobilite şirketinde operasyon birimindeyim; müşterilerin acil ihtiyaçlarına yanıt veriyorum, personel çizelgelerini kontrol ediyorum ve "acil" olanları henüz krize dönüşmeden temizliyorum. Öğleden sonraları ise iş geliştirme: dış aramalar, satış havuzu (pipeline) incelemeleri ve geniş ölçekli ikna süreçleri.

    İki rol. Tek kişi. Birbirine zıt talepler.

    Benim "Operasyon" versiyonum bugünü onarıyor. "Satış" versiyonum ise geleceğin peşinde koşuyor. Tam ortada ise bir darboğaz duruyor: ben. İki hayat arasındaki her devir-teslim zihnimin içinde gerçekleşiyor; bu da her bağlam değişimi (context switch) için bir bedel ödemem gerektiği anlamına geliyor: zaman, enerji ve bilişsel keskinlik.

    Bundan kendi çabamla kurtulmaya çalıştım. Daha iyi takvim sistemleri, daha katı zaman blokları, daha akıllı önceliklendirmeler… Hiçbiri ihtiyacım olan seviyede işe yaramadı. Sorun verimlilik değildi. Sorun, insani eylem gücünün tavan çizgisiydi: Kendimi tükenmişliğin eşiğine kadar optimize edebilir, ama yine de kendi rollerim arasındaki bağlayıcı olmanın yarattığı temel darboğazdan kaçamazdım.

    Ben Buradan Daha Önce Geçtim

    Bu sürtünme benim için yeni değil. Daha önce de yürüttüğüm bir modelde de tecrübe ettim, sadece araçlar farklıydı.

    1998 yılında, gıda ambalajı sektöründe sıfırdan bir üretim tesisi kurdum. Yüzlerce alt görevden oluşan süreğen bir iş ve işletme büyüdükçe sürekli evrilen gereksinimler… Çözümüm, bugün de başvuracağım içgüdüyle aynıydı: sistemlerle düşünmek. Her süreci olabildiğince tekrarlanabilir ve "sıkıcı" hale getirmek. Delege etmek. Adımları değil, sonuçları denetlemek.

    Oradan ayrıldığımda, bu yaklaşım ortaya üç klasör (ISO 9001, ISO 22000 ve ISO 14001) ve kendi ivmesiyle çalışan bir üretim tesisi çıkarmıştı.

    Ondan da önce, bir dil okulunun operasyonlarını koordine ediyordum: ön ofisi yöneten bir yönetici ve üç satış personeli, arka planda ise yirmi öğretmenle işi yürüten ben. Farklı sektör, aynı mimari: Sistemi elinde tut, icraatı delege et, sonuçları denetle.

    O klasörler benim kontrol mekanizmamdı; öğretmenler ise benim aracılarımdı (agents). Sadece o zamanlar henüz bu terminolojiye sahip değildim.

    Yöntem değişmedi ama kısıtlar değişti. Eskiden bu tür bir eylem gücü inşa etmek koca bir ekip gerektirirdi ve insanlardan oluşan ekipler maliyetlidir. Kötü günleri olur. Odakları dağılır. İşten ayrılırlar. Sürekli olarak yüksek eylem gücüne sahip insanlardan oluşan bir ekip kurmak, her organizasyonun en zor problemlerinden biridir. Bugün ise kısıt, çalışan sayısı değil, konfigürasyondur.

    Otomasyondan Orkestrasyona

    Çıkış yolu bir "gölge proje" olarak başladı; kenarda köşede inşa ettiğim, henüz neye dönüşeceğinden emin olmadığım bir şey.

    Önce otomasyonla başladı. "Şu olursa şunu yap" kuralları: CRM güncellemelerini otomatik kaydet, destek taleplerini anahtar kelimeye göre yönlendir, takip dizilerini tetikle. Yararlıydı ama dardı. Lineer otomasyon, net girdileri ve öngörülebilir adımları yönetir. Ancak karmaşık ve yüksek bağlam gerektiren geçişlerde (müşterinin alışılmadık bir talepte bulunduğu bir satış görüşmesi veya net bir kategorisi olmayan bir operasyonel sorun gibi) çöker.

    Kırılma noktası, otomasyon kurmayı bırakıp bir orkestrasyon katmanı inşa etmeye başladığımda yaşandı; kuralları uygulayan değil, bağlamlar arasında muhakeme yürüten bir yapay zekâ ajanları sistemi. Bu da farklı bir düşünme biçimi gerektiriyordu: "Hangi yapay zeka aracı en iyisi?" değil, "Bu özel iş için hangi yapay zeka doğru?" sorusu.

    İş Geliştirme (BD) için, görüşme sonuçlarını analiz etmek ve sistemler kurmak için Claude'u; potansiyel müşteri araştırması ve web taraması için Gemini'yi kullanıyorum. Yan proje olarak yürüttüğüm İş İngilizcesi öğrenme platformu içinse, kıdemli yazılımcı olarak Claude'u, müfredat uzmanı olarak Gemini'yi seçtim; çünkü Gemini'nin eğitimi onu yabancı dil eğitimi (EFL) kaynakları konusunda daha güçlü kılıyordu. Kendi güçlü yanlarına göre değerlendirilen iki farklı model, aynı sistem içinde çalışıyor.

    Pratikte şöyle görünüyor: Teams üzerinde karmaşık bir satış görüşmesi sona eriyor. Orkestrasyon katmanım transkripti okuyor, verdiğim her operasyonel sözü tanımlıyor, mevcut destek yüküyle çapraz kontrol yapıyor ve ben daha başka bir pencere açmadan bir devir-teslim özeti taslağı hazırlıyor. Manuel not tutmak yok. Satış ve Operasyon kimliklerim arasında çeviri yaparken kaybolan bağlam yok. Sistem ipin ucunu tutuyor, böylece benim tutmama gerek kalmıyor.

    Aynı gölge proje sonunda platformun kendisine dönüştü: Yapay zekâ destekli, yetişkin İngilizce öğrenenler için inşa edilmiş ve günlük işimin yanında tıkır tıkır işleyen bir sistem. Aynı orkestrasyon prensibi burada da geçerli: ders üretimi, öğrenci geri bildirim analizi ve müfredat sıralaması… Hepsi benim manuel olarak yürüttüğüm değil, denetlediğim bir sistem üzerinden ilerliyor. Artık iki kanal aynı saatler için rekabet etmiyor. Her ikisinin arkasındaki niyeti anlayan bir katman sayesinde birbirine bağlı şekilde, paralel çalışıyorlar.

    Kaldıracı Olmayan Çok Kanallı Operatör

    Çok kanallı yaşam artık norm haline geliyor. Mevcut işlerin yanında ilerleyen girişimler. Operasyonel işlerin yanında yaratıcı çalışmalar. Tek kanallı kariyer, 20. Yüzyılından kalma bir eserdir.

    Ancak her kanalda asıl işçi olarak kalmaya devam ederseniz, çok kanallı hayat bir tuzaktır. Teknik bir kaldıracınız —farklı rollerinizin bağlamını anlayan bir orkestrasyon katmanınız— yoksa, birden fazla kanalı yönetmiyorsunuzdur. Sadece bitkinsinizdir.

    Bu tür bir eylem gücüne giden eski yol bir ekip gerektiriyordu: koordinatörler, yöneticiler, satış personeli ve üretim ekipleri. İnsan ekipleri pahalıdır, tutarsızdır ve ölçeklendirilmesi zordur. Ajanların ise —doğru konfigüre edildiklerinde— kötü günleri olmaz. Yeni kısıt çalışan sayısı değil; niyetin netliği ve kurulumun kalitesidir.

    Gelecek nesil profesyoneller, ne kadar çok şey yapabildikleriyle tanımlanmayacaklar. Ne kadar etkili orkestrasyon yapabildikleriyle tanımlanacaklar: Niyetlerini bağlamlar arasında taşıyan, işi akıllıca devreden ve saatleri katlamadan çıktıyı katlayan sistemler inşa etmek.

    Artık Satış ve Operasyonu yönetmiyorum. Onları birbirine bağlayan sistemi denetliyorum ve aynı mimariyi yan tarafta kendime ait bir şey inşa etmek için kullanıyorum.

    Hedef, daha iyi bir dişli olmak değil. Hedef, makineyi inşa etmek ve sonra bir adım geri çekilip sırada neyin olduğunu kurgulamaktır.

  • The Architect’s Leap: Orchestrating Agency in a Multi-Track World

    The Architect’s Leap: Orchestrating Agency in a Multi-Track World

    Agency is not the ability to work harder. It's the ability to shrink the distance between an intention and its execution. In a world built to reward specialization, the most valuable competitive advantage isn't a deeper skill set — it's a better system. True agency arrives the moment you stop being the engine and start being the architect.


    The Multi-Track Friction

    In my current role, my daily reality has looked like this: mornings in Operations at an urban mobility company — answering immediate client and customer needs, checking staff schedules, clearing the urgent before it becomes a crisis. Afternoons in Business Development — outbound calls, pipeline reviews, persuasion at scale.

    Two roles. One person. Opposite demands.

    The Ops version of me is fixing the present. The Sales version is hunting the future. In the middle sits a bottleneck: me. Every hand-off between the two lives in my head, which means every context switch costs something — time, energy, cognitive sharpness.

    I tried to manage my way out of it. Better calendar systems, stricter time blocks, smarter prioritization. None of it worked at the level I needed. The problem wasn't efficiency. It was the ceiling of human agency: I could optimize myself to the edge of burnout and still not escape the fundamental bottleneck of being the connector between my own roles.


    I've Been Here Before

    This friction isn't new to me. It's a pattern I've run before — just with different tools.

    In 1998, I built a production facility from a green site in the food packaging sector. One ongoing task, hundreds of sub-tasks, and constantly evolving requirements as the business grew. My solution was the same instinct I'd reach for today: think in systems. Make every process as repeatable and boring as possible. Delegate. Supervise outcomes, not steps.

    By the time I walked away, that approach had produced three binders — ISO 9001, ISO 22000, and ISO 14001 — and a production facility running on its own momentum.

    Before that, I coordinated operations for a language school: one administrator and three sales staff managing the front office, me running the backend with twenty teachers. Different industry. Same architecture. Hold the system, delegate execution, supervise outcomes.

    Those binders were my harness and my evals. The teachers were my agents. I just didn't have that language yet.

    The method hasn't changed. The constraint has. Building that kind of agency used to require a whole team — and human teams are expensive. They have bad days. They misalign. They leave. Finding a team of consistently high-agency people is one of the hardest problems in any organization. Today, the constraint is configuration, not headcount.


    From Automation to Orchestration

    The way out started as a shadow project — something I was building in the margins, not yet sure what it would become.

    It started with automation. If-This-Then-That rules: auto-log CRM updates, route support tickets by keyword, trigger follow-up sequences. Useful, but narrow. Linear automation handles clean inputs and predictable steps. It breaks down at the messy, high-context handoffs — a sales call where a client made an unusual request, an ops issue with no clean category.

    The pivot came when I stopped building automations and started building an orchestration layer — a system of AI agents that reason across context rather than execute rules. And that required a different kind of thinking: not "which AI tool is best," but "which AI is right for this specific job."

    For BD, I use Claude to analyze call outcomes and build systems, and Gemini to research prospects and scrape the web. For the Business English learning platform I'm building in the margins, I chose Claude as the senior developer and Gemini as the curriculum expert — specifically because Gemini's training made it a stronger EFL resource. Two different models, evaluated for their strengths, are working in the same system.

    Here's what that looks like in practice: a complex sales call ends on Teams. My orchestration layer reads the transcript, identifies every operational commitment I made, cross-references current support load, and drafts a hand-off summary — before I've opened another window. No manual note-taking. No context lost in translation between my Sales and Ops selves. The system holds the thread, so I don't have to.

    That same shadow project eventually became the platform itself — AI-powered, built for adult English learners, running alongside the day job. The same orchestration principle applies: lesson generation, student feedback analysis, and curriculum sequencing — all running through a system I oversee rather than manually operate. The two tracks no longer compete for the same hours. They run in parallel, connected by a layer that understands the intent behind both.


    The Multi-Track Operator Without a Lever

    The multi-track life is becoming the norm. Day jobs alongside companies in progress. Creative work alongside operational work. The single-track career is a 20th-century artifact.

    But the multi-track life is a trap if you remain the primary laborer on every track. Without a technical lever — an orchestration layer that understands the context of your different roles — you're not running multiple tracks. You're just exhausted.

    The old path to this kind of agency required a team: coordinators, administrators, sales staff, and production crews. Human teams are expensive, inconsistent, and hard to scale. Agents don't have bad days — once they're properly configured. The new constraint isn't headcount. It's clarity of intent and quality of setup.

    The next generation of professionals won't be defined by how much they can do. They'll be defined by how effectively they can orchestrate: building systems that carry their intent across contexts, hand off work intelligently, and multiply output without multiplying hours.

    I'm not managing Sales and Ops anymore. I'm overseeing the system that connects them — and using the same architecture to build something of my own on the side.

    The goal isn't to be a better cog. The goal is to build the machine, and then step back and architect what comes next.

  • Your AI Tutor is Making You Worse at English

    You've been using ChatGPT as your English tutor. You paste in a paragraph, it fixes your grammar, suggests better phrasing, maybe even rewrites it in a more "professional" tone. You copy the result, send the email, and feel like you've leveled up.

    You haven't.

    What just happened is the AI practiced writing professional English. You practiced copying and pasting.

    The Crutch Problem

    In second language acquisition, there's a concept called fossilization. It's what happens when a learner's errors become permanent — baked into their production (speaking, writing) so deeply that no amount of correction dislodges them.

    Generic AI accelerates this in a way that textbooks never could. Here's the cycle:

    1. You write something with errors.
    2. The AI corrects it instantly.
    3. You see the correction, think "ah, right," and move on.
    4. Tomorrow, you make the same error. The AI corrects it again.
    5. Repeat for months.

    The problem isn't that the AI is wrong — its corrections are usually excellent. The problem is that seeing a correction is not the same as producing it. Your brain encoded the error when you wrote it. The correction arrives too late to prevent that encoding. Over time, you build two competing patterns: the wrong one you keep producing and the right one you keep reading. The wrong one wins because it has more production reps.

    What "Errorless" Means

    At CareerTalkLab, we took a different approach. Our engine is built on a behavioral science principle called Errorless Teaching. The core idea: if the learner never produces the error, the error never gets encoded.

    Instead of test-then-correct, we scaffold:

    • First, you see the correct form in a realistic professional context.
    • Then, you recognize it among alternatives (with heavy support).
    • Then, you produce it with partial cues.
    • Finally, you produce it independently.

    By the time you're on your own, the correct form is the only one you've ever practiced. There's no competing error pattern to fight against.

    "But I Need Help Writing Emails Right Now"

    Fair. And there's nothing wrong with using AI to polish a specific email for a specific meeting. The problem is when that becomes your learning strategy.

    Think of it like navigation. Using GPS to get to a new restaurant is fine. Using GPS for your daily commute means you never learn the route. Three years in, you still can't drive to work without your phone.

    If you're using AI to fix your English, you're getting to the restaurant. If you want to actually learn the route, you need a system that builds the muscle — not one that drives for you.

    Try a Different Approach

    The A1 Sprint at CareerTalkLab is free. Every lesson is a professional scenario — pitches, updates, dashboards — built on Errorless Teaching. No crutches. Real production.

    Sign up and take the diagnostic quiz at CareerTalkLab.com.


    CareerTalkLab is a learning engine for global professionals. Read more about the Errorless Teaching framework.

  • Why Generic AI is Failing Professional English Learners

    Most people think that having ChatGPT or Claude as a "tutor" is a breakthrough for language learning. They aren't wrong—it's a massive leap forward. But for a professional who needs more than just "conversation," generic AI has a hidden flaw: it is too helpful.

    When an LLM corrects your grammar after you make a mistake, or provides a perfect translation when you get stuck, it isn't actually teaching you. It is acting as a "crutch." In pedagogical terms, this often leads to fossilization—where incorrect forms become deeply embedded because the learner is relying on the AI to "clean up" their output rather than building the internal muscle to produce it correctly the first time.

    The "Confidence Gap" in Global Teams

    In my years as an Education Coordinator, I saw this "Confidence Gap" play out daily. Professionals would spend hours on generic apps, only to freeze when asked to explain a project dashboard or a complex quarterly report in a high-stakes meeting.

    The core skill they were missing wasn't grammar — it was data narration. Describing charts, explaining trends, telling the story behind a performance spike or a churn table. If you can't narrate your dashboard, your expertise is essentially invisible. That's the skill that turns a technical expert into a strategic leader, and it's exactly what generic conversation practice never trains.

    Introducing CareerTalkLab: The Errorless Teaching Framework

    This is why I moved from leading digital transitions in traditional schools to architecting a different kind of system. We don't need more "chatbots." We need a High-Fidelity Sandbox.

    At CareerTalkLab, we've systematized a behavioral science principle called Errorless Teaching into our core architecture. Our system uses a Prompt-Fading Methodology that moves a learner through four distinct phases:

    1. Receptive Orientation: Seeing the target language in a professional context (e.g., a technical IT ticket).
    2. Guided Recognition: Identifying the correct "chunks" of language with high-density scaffolding.
    3. Guided Production: Producing language with partial cues, ensuring an 80%+ success rate.
    4. Independent Performance: Using the language in a realistic, unscripted scenario.

    By ensuring the learner succeeds on the first try, we prevent the "fossilization" of errors and build genuine psychological safety.

    Engineering for Pedagogy (The "Lab" Approach)

    As the Lead Architect, my goal wasn't just to build an interface. I wanted to build a Content Engine.

    • The News-to-Lesson Pipeline: We've built a system that transforms real-time industry news into GSE-aligned (Global Scale of English) interactive lessons. This means a professional isn't learning from a 10-year-old textbook; they are practicing with the news that broke in their industry this morning.
    • Architecture for Custom Models: Our system is designed for custom model integration — enabling pedagogical rules and professional discourse constraints that off-the-shelf models simply aren't built for.

    The Seed is Planted

    CareerTalkLab is the "seed" of what I believe will be a new standard for professional development. It's not just about "learning English" — it's about Professional Synchronization. It's about ensuring that global teams can communicate their narratives with the same precision they bring to their code or their strategy.

    The Lab is live. You can sign up, take the diagnostic quiz, and start your first briefing today at CareerTalkLab.com.

    If you are a professional looking to bridge your own "Confidence Gap," or an L&D leader tired of generic tools, I'd welcome you in the sandbox.

  • Why Your Best Engineers Can’t Explain Their Own Work

    Your lead engineer just shipped a feature that reduced API response time by 40%. In the retro, when asked to walk the team through what they did and why it matters, they say: "I fixed the database queries. It is faster now."

    That's not a communication failure. It's an invisibility problem.

    The technical work happened. The results are in the metrics. But the narrative — the part that gets you promoted, that gets your project funded, that gets leadership to understand why your team matters — never made it out of the engineer's head.

    The Skills Gap Nobody Talks About

    In global tech teams, this gap is everywhere. Engineers, product managers, and analysts who are genuinely brilliant at their work but cannot narrate their contributions in English at the level their role demands.

    They can write code comments. They can follow documentation. They can even hold a casual conversation over lunch. But when the context shifts to high-stakes — a quarterly review, a client presentation, a cross-functional strategy session — they default to simplified, stripped-down English that undersells their expertise.

    The problem isn't vocabulary. It's register. The ability to shift from casual to strategic. From "I fixed it" to "We identified a bottleneck in the query layer that was adding 200ms to every authenticated request. By restructuring the join logic and introducing a caching layer, we reduced P95 latency by 40%, which directly impacts our SLA commitments."

    Same person. Same knowledge. Completely different professional impact.

    Why Generic Tools Don't Fix This

    Most language learning tools are built for general conversation. They'll help you order coffee or describe your weekend. Useful skills — but they don't train the specific register shift that professionals need.

    And generic AI chatbots? They'll happily rewrite your sentence for you. Which means they're practicing the skill, not you. In language acquisition, this creates a dependency loop. The AI becomes a crutch, and the professional never builds the internal muscle to produce strategic-level English independently.

    What Actually Works

    At CareerTalkLab, we built the A1 Sprint specifically around professional tasks. Every lesson is framed as a workplace scenario:

    • The 30-Second Company Pitch — not "introduce yourself"
    • Narrating a Weekly Dashboard — not "describe a picture"
    • The Project Status Update — not "write a paragraph about your day"

    The underlying engine uses a methodology called Errorless Teaching. Instead of letting you fail and then correcting you, it scaffolds you into producing the correct form on the first attempt. The error pattern never gets reinforced. Over 31 lessons, you build the muscle memory of professional-grade production.

    The Real ROI

    For the professional: the ability to narrate your own expertise is the difference between being a contributor and being a leader.

    For the organization: every engineer who can articulate their work clearly is one fewer bottleneck in cross-functional communication. That's not a "soft skill" — it's operational efficiency.

    Start Free

    The A1 Sprint is free. Take the diagnostic quiz and begin your first briefing at CareerTalkLab.com.


    CareerTalkLab is a learning engine for global professionals. Read more about our Errorless Teaching framework.

  • What is Errorless Teaching — and Why Does It Work for Adult Professionals?

    Most language apps follow the same playbook: throw a question at you, let you fail, then show you the answer. It feels productive. You're "learning from mistakes."

    Except you're not.

    In behavioral science, this approach has a well-documented failure mode called fossilization. When a learner produces an error and then sees the correction, the error itself gets encoded alongside the correct form. Over time, the wrong version becomes just as automatic as the right one. For a professional who needs to sound confident in a board meeting next Tuesday, that's not a learning strategy — it's a liability.

    The Alternative: Errorless Teaching

    Errorless Teaching flips the model. Instead of test-then-correct, it scaffolds the learner into succeeding on the first attempt. The correction never needs to happen because the error never occurs.

    This isn't theory. It's a methodology with decades of research behind it, originally developed for high-stakes clinical settings where errors carry real consequences. At CareerTalkLab, we've systematized it into four phases:

    Phase 1 — Receptive Orientation

    The learner encounters the target language in a realistic professional context. No production pressure. You're reading a technical email, scanning a project update, hearing a team standup. The goal is pattern recognition, not recall.

    Phase 2 — Guided Recognition

    Now we ask you to identify the right form — but with heavy scaffolding. Distractors are obviously wrong. The correct answer is practically highlighted. You're building confidence, not being tested.

    Phase 3 — Guided Production

    You produce the language, but with partial cues still visible. A sentence frame, a word bank, a structural hint. The scaffolding fades, but it's still there. Our target: 80%+ success rate. If you're falling below that, the system increases support automatically.

    Phase 4 — Independent Performance

    Full production. No cues. A realistic scenario — narrating a dashboard, pitching a project, writing a status update. By this point, the correct form is what you've practiced every time. The error pattern was never reinforced.

    Why This Matters for Professionals

    Generic language apps treat every learner the same: a student. But a senior engineer who freezes when explaining a latency spike to leadership doesn't need more grammar drills. They need a system that builds the muscle memory of correct production in their specific professional context.

    That's what we built at CareerTalkLab. The A1 Sprint is structured entirely around professional tasks — not textbook units. You won't find "Unit 4: Present Simple." You'll find "The 30-Second Company Pitch" and "Narrating Your Weekly Dashboard."

    Try It

    The A1 Sprint is free. Sign up, take the diagnostic quiz, and start your first briefing at CareerTalkLab.com.


    CareerTalkLab is a learning engine for global professionals, built on Errorless Teaching and powered by AI. Learn more about why generic AI fails professional learners.

  • Hello, World

    I've always been a writer in my head — turning over ideas during a commute, drafting arguments in the shower, composing paragraphs while falling asleep. The problem was never a lack of things to say. It was the gap between thinking and publishing.

    So here's the deal: this blog will be a mix of whatever's on my mind. That means professional topics — data, operations, technology — alongside more personal writing about food, travel, and the strange overlaps between all of those things.

    Why now?

    Honestly, building this site forced my hand. Once the scaffolding was up, an empty blog directory felt like an accusation. So here we are.

    What to expect

    I'm not committing to a schedule. What I'll commit to is writing when I have something worth saying — and trying to say it well.

    If any of it resonates, I'd love to hear from you via the contact page.

    Thanks for reading.

  • Building This Site

    I wanted a personal site that felt deliberate — not a template with my name swapped in. Here's how it came together and some of the tradeoffs I made along the way.

    Stack

    The site runs on Next.js 15 with the App Router and is deployed on Vercel. Content (including this post) is written in Markdown and rendered with next-mdx-remote at build time, which means zero client JavaScript for reading a blog post.

    Tailwind CSS handles all styling. I was skeptical of utility-first CSS for years, but after using it on a few projects I've come around. The bento grid layout on the home page would have been painful to maintain with traditional CSS.

    The bento grid

    The layout on the home page is a 12-column bento grid — a design pattern popularized by Apple's product pages. Each box has a configurable span prop, so it's easy to rearrange sections without touching layout code.

    <BentoBox span={8} variant="gradient">
      <AboutTeaserBox />
    </BentoBox>
    

    Content pipeline

    All written content (about, portfolio case studies, recipes, blog posts) lives in a content/ directory as Markdown files with YAML frontmatter. A single content.ts utility handles reading, parsing, and sorting — so adding a new content type is as simple as creating a new subdirectory.

    What I'd do differently

    • Database-backed content. Flat files are fast to start with, but editing from a phone is painful. I'd consider a headless CMS for anything that needs frequent updates.
    • More aggressive image optimization. Next.js <Image /> helps, but I haven't done a proper audit of the assets yet.

    Overall, it was a satisfying build. The constraint of keeping it simple actually pushed me toward better decisions.