I want to start with a moment that should be easy. Imagine an A1 learner — call her Ayşe, six weeks into her first Business English course — typing this into a practice box:
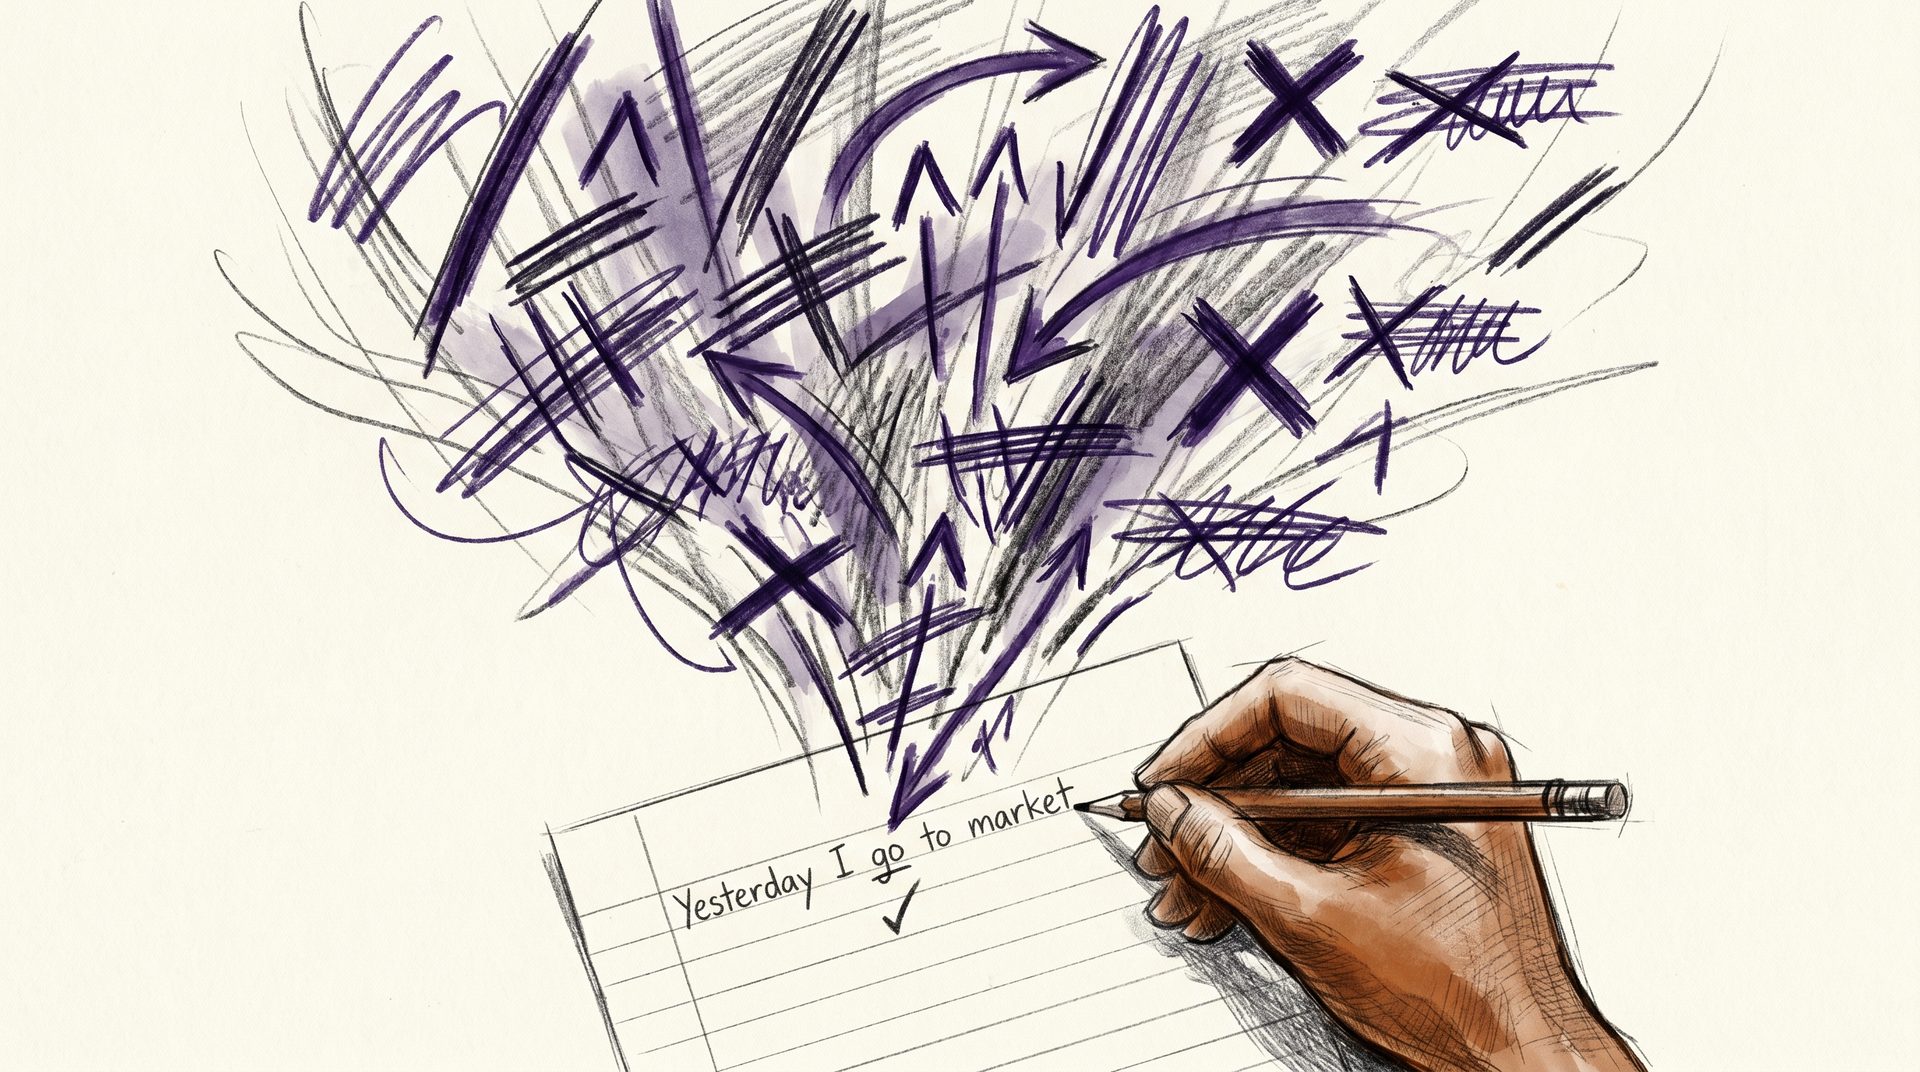
Yesterday I go to market and I buy bread.
A model might return:
Yesterday, I went to the market and bought some bread.
Fluent? Yes. Useful feedback? That depends on what Ayşe is practicing.
For this example, suppose the teacher has introduced one small target: using went rather than go to describe yesterday. The exercise is a scaffolded practice turn, not a test of the entire past tense or article system. The rewrite changes the target verb, a second verb, the article before market, and the phrasing around bread. It supplies a finished sentence without asking Ayşe to practice the target herself.
A response aligned with that narrow objective could be:
You told me when it happened: yesterday. For yesterday, use went instead of go. Try that part again.
That response does not certify the whole sentence as correct. It gives Ayşe one manageable next step. Other features can be addressed when they become the lesson target.
This is what I mean by the machine is wrong: a response can be linguistically accurate and still miss the instructional purpose. For CareerTalkLab (CTL), in our English as a Foreign Language (EFL) section, the design challenge is to make that purpose explicit.
Why it fails
Frontier models can produce fluent rewrites and discuss language-learning frameworks. Neither ability guarantees that a particular feedback turn serves a particular learner. The failure mode has three layers.
Insufficient learner context. Knowing about the Common European Framework of Reference for Languages (CEFR) or Pearson’s Global Scale of English (GSE) is different from knowing what Ayşe has actually been taught. A level label does not tell the tutor which vocabulary is familiar, which structure is being practiced, or what the previous attempt showed. The tutor needs the lesson target, relevant learning history, and a clear policy on what to correct.
The level references need precision too. Pearson’s adult GSE grammar guide lists A1 as GSE 22–29. It places basic a/an objectives at A1 and broader article selection later. Articles are not simply a “B1 problem.” The practical question is whether this use has been introduced to this learner for this task.
Insufficient first-language context. Turkish and English organize grammar differently, including article use and tense/aspect. Those differences can help a teacher anticipate possible first-language (L1) transfer. A model may know about such patterns, but reliable feedback requires applying that knowledge carefully to the learner’s actual error. A learner’s L1 is useful context, not a diagnosis: a single sentence does not establish why an error occurred.
An unspecified correction policy. CTL’s beginner instruction draws on Applied Verbal Behavior and errorless teaching approaches, using prompts and scaffolds to support successful practice. Selective correction is one part of the policy for narrowly targeted exercises; it is not the whole definition of errorless teaching, or a universal rule for EFL.
Broader corrective feedback can be useful in other settings. For example, research on an online EFL writing course found benefits from unfocused indirect feedback combined with additional practice tasks. That context differs from a beginner’s short practice turn. The correction policy should follow the learner, task, and objective.
So the model’s fluency is not the problem by itself. The problem is fluency without a sufficiently specified teaching task.
The loop
The teacher owns the instructional decisions. The model can assist, but the surrounding system must carry the constraints and check whether they survive generation. Here is the design I want CTL’s feedback loop to follow.
Constrain the tutor before generation. Give it the target structure, familiar language, relevant prior attempts, and examples of acceptable feedback. Include examples of what to leave for later. Worked examples make the intended behavior concrete; their benefit still needs to be tested against the same rubric as any other prompting choice.
Evaluate the response before delivery. A separate judge can score feedback against a lesson-specific rubric: level appropriateness, target reinforcement, correction scope, and tone. A failed response can be regenerated with the failure reason supplied as context.
But a second model is not an independent authority merely because it has a different role. It can share the tutor’s blind spots. The judge needs calibration against expert-reviewed examples, checks for missed failures and false alarms, and an option to mark a case uncertain. Anthropic’s evaluation guidance likewise recommends calibrating model graders with human experts.
Retries need a limit. If the system cannot produce acceptable feedback within that limit, it should use a teacher-approved fallback or hold the turn for review rather than keep generating until something passes. Cost, latency, and incorrect approvals belong in the evaluation alongside the rubric score.
Keep human review upstream. A human learner reviewed every lesson before soft launch. Lesson design is where mistakes can compound: an unclear objective or a poorly chosen scaffold can shape many subsequent feedback turns. Reviewing the lesson first reduces the burden on the runtime judge.
Let the learner challenge the feedback. A low-friction “this correction was off” signal can expose problems our test set missed. The learner is the authority on confusion and frustration, but the flag alone does not establish that the language correction was wrong.
The loop should be flag → expert review → expected response → regression test. Reviewers need enough lesson and conversation context to distinguish an incorrect correction from an unclear explanation, a level mismatch, or a valid correction the learner has not understood. Confirmed cases can become tests of the behavior we want to preserve. A raw flag is a candidate failure case, not automatically a labeled training example.
The pattern is constrained generation, evaluated generation, observed generation. For CTL’s learner-facing feedback, I want all three.
The broader lesson
The temptation when building with frontier models is to treat general capability as proof of domain suitability. A fluent answer is only one dimension of success. In teaching, we also care about what the learner notices, practices, and can later do without assistance.
For builders in expert domains, the lesson is the same: the model is not the product. The product includes the task definition, constraints, review process, and evidence that the whole system performs its intended job.
Domain experts should define those objectives and validate the examples. Models can help propose rules and draft rubrics, but their proposals still need review. Delegating generation does not remove responsibility for instructional decisions.
What this means for the CTL roadmap
These were the design priorities heading into beta in May 2026. They describe the intended release policy, not measured evidence that the complete loop has already met it.
The eval suite belongs on the critical path. Before expanding into B1+ lessons, define an acceptable level-mismatch rate, assemble an expert-reviewed test set, and check performance by learner level and lesson target. A high aggregate pass rate should not hide a weak category.
Learner feedback belongs in the core workflow too. Collecting flags is only the start; the review process must turn confirmed problems into actionable examples and regression tests.
The initial beta focus is Turkish A1/A2 learners. Keeping the cohort narrow makes it easier to examine whether the feedback matches those learners’ tasks and needs before broadening the audience. It is a scope decision, not a claim that L1 transfer is necessarily strongest at those levels.
The IELTS track should remain gated until the Executive track’s feedback quality is stable against agreed criteria. One track at a time, with empirical testing guiding expansion.
To show whether this design works, we need to report more than judge scores: expert-confirmed failure rates, disagreement between experts and the judge, feedback latency, and evidence that learners can use the target in a later attempt. Those are the results a follow-up should examine.
The machine can be right about English and wrong about the next teaching move. Trust has to be earned on each instructional task. That is the design principle for CTL.