Tag: AI

  • The Machine is Wrong: Designing AI Feedback Loops for EFL

    The Machine is Wrong: Designing AI Feedback Loops for EFL

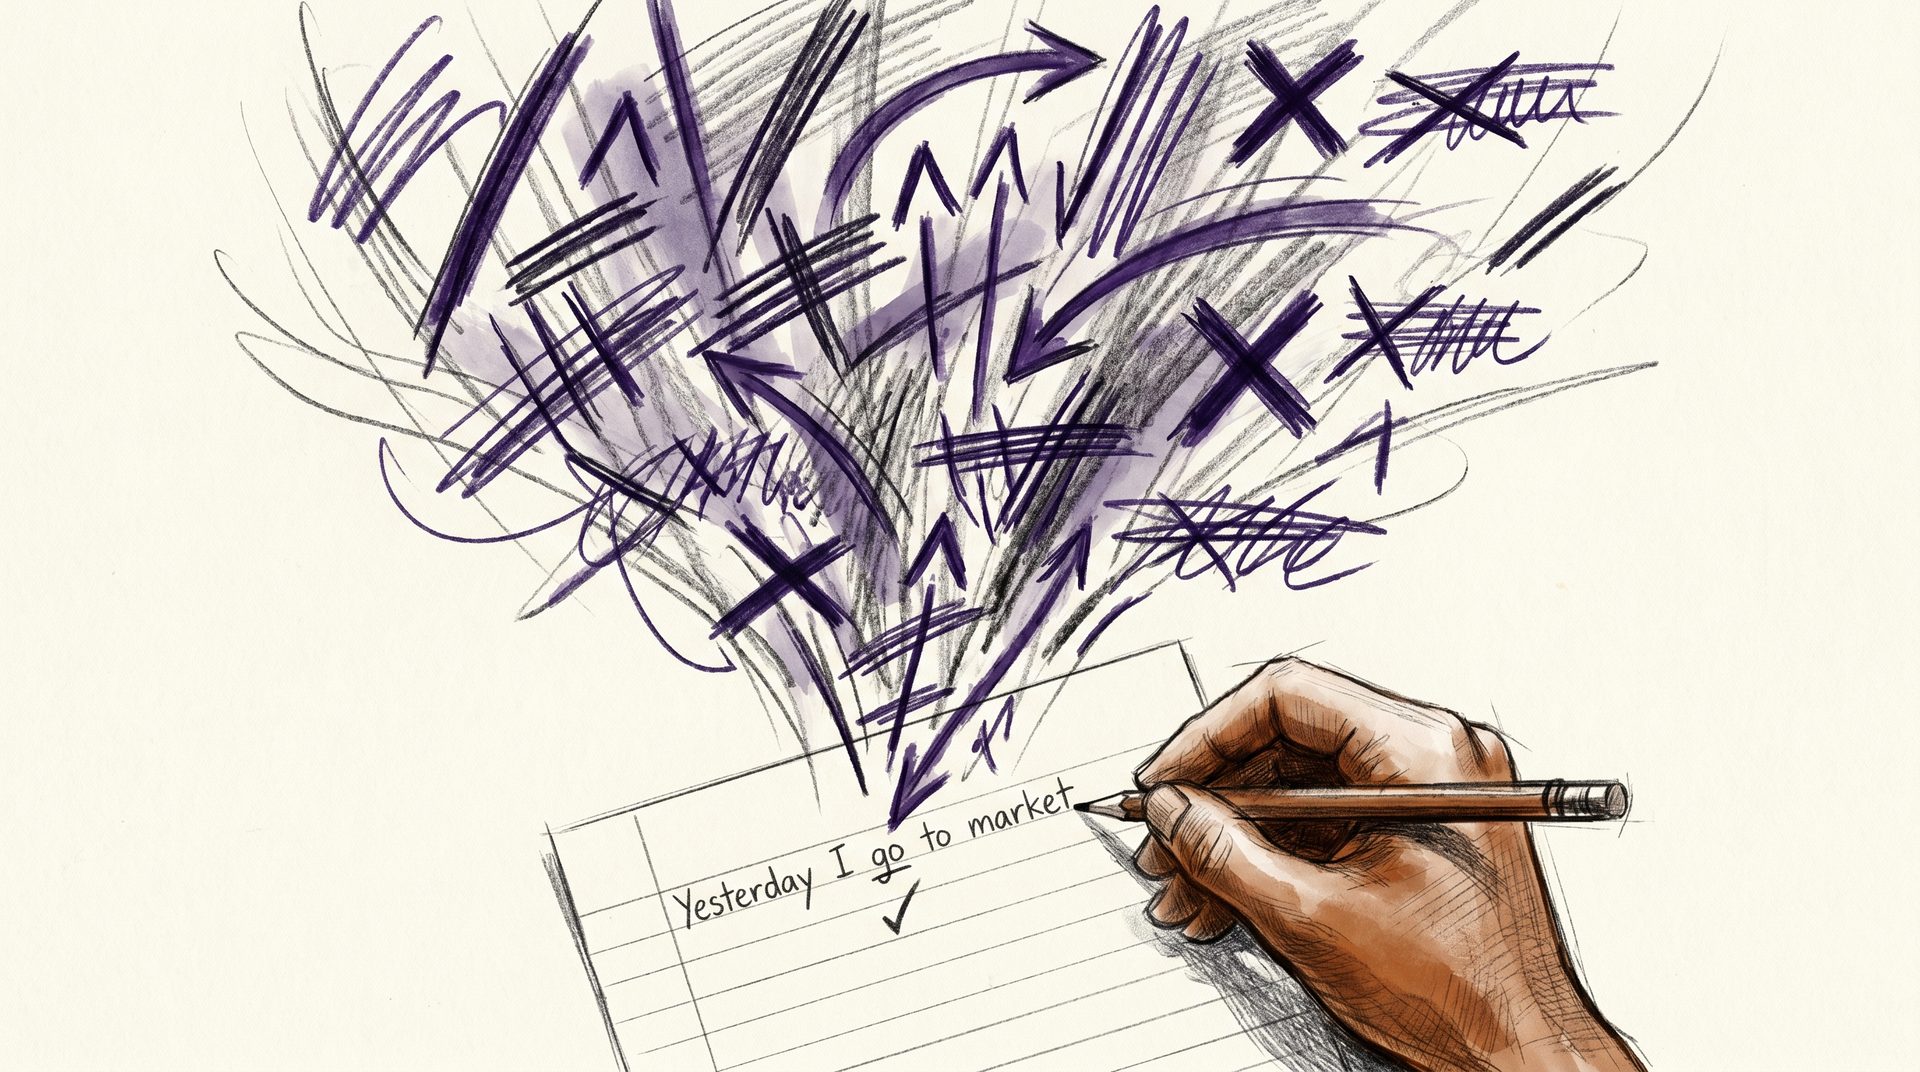
    I want to start with a moment that should be easy. Imagine an A1 learner — call her Ayşe, six weeks into her first Business English course — typing this into a practice box:

    Yesterday I go to market and I buy bread.

    A model might return:

    Yesterday, I went to the market and bought some bread.

    Fluent? Yes. Useful feedback? That depends on what Ayşe is practicing.

    For this example, suppose the teacher has introduced one small target: using went rather than go to describe yesterday. The exercise is a scaffolded practice turn, not a test of the entire past tense or article system. The rewrite changes the target verb, a second verb, the article before market, and the phrasing around bread. It supplies a finished sentence without asking Ayşe to practice the target herself.

    A response aligned with that narrow objective could be:

    You told me when it happened: yesterday. For yesterday, use went instead of go. Try that part again.

    That response does not certify the whole sentence as correct. It gives Ayşe one manageable next step. Other features can be addressed when they become the lesson target.

    This is what I mean by the machine is wrong: a response can be linguistically accurate and still miss the instructional purpose. For CareerTalkLab (CTL), in our English as a Foreign Language (EFL) section, the design challenge is to make that purpose explicit.

    Why it fails

    Frontier models can produce fluent rewrites and discuss language-learning frameworks. Neither ability guarantees that a particular feedback turn serves a particular learner. The failure mode has three layers.

    Insufficient learner context. Knowing about the Common European Framework of Reference for Languages (CEFR) or Pearson’s Global Scale of English (GSE) is different from knowing what Ayşe has actually been taught. A level label does not tell the tutor which vocabulary is familiar, which structure is being practiced, or what the previous attempt showed. The tutor needs the lesson target, relevant learning history, and a clear policy on what to correct.

    The level references need precision too. Pearson’s adult GSE grammar guide lists A1 as GSE 22–29. It places basic a/an objectives at A1 and broader article selection later. Articles are not simply a “B1 problem.” The practical question is whether this use has been introduced to this learner for this task.

    Insufficient first-language context. Turkish and English organize grammar differently, including article use and tense/aspect. Those differences can help a teacher anticipate possible first-language (L1) transfer. A model may know about such patterns, but reliable feedback requires applying that knowledge carefully to the learner’s actual error. A learner’s L1 is useful context, not a diagnosis: a single sentence does not establish why an error occurred.

    An unspecified correction policy. CTL’s beginner instruction draws on Applied Verbal Behavior and errorless teaching approaches, using prompts and scaffolds to support successful practice. Selective correction is one part of the policy for narrowly targeted exercises; it is not the whole definition of errorless teaching, or a universal rule for EFL.

    Broader corrective feedback can be useful in other settings. For example, research on an online EFL writing course found benefits from unfocused indirect feedback combined with additional practice tasks. That context differs from a beginner’s short practice turn. The correction policy should follow the learner, task, and objective.

    So the model’s fluency is not the problem by itself. The problem is fluency without a sufficiently specified teaching task.

    The loop

    The teacher owns the instructional decisions. The model can assist, but the surrounding system must carry the constraints and check whether they survive generation. Here is the design I want CTL’s feedback loop to follow.

    Constrain the tutor before generation. Give it the target structure, familiar language, relevant prior attempts, and examples of acceptable feedback. Include examples of what to leave for later. Worked examples make the intended behavior concrete; their benefit still needs to be tested against the same rubric as any other prompting choice.

    Evaluate the response before delivery. A separate judge can score feedback against a lesson-specific rubric: level appropriateness, target reinforcement, correction scope, and tone. A failed response can be regenerated with the failure reason supplied as context.

    But a second model is not an independent authority merely because it has a different role. It can share the tutor’s blind spots. The judge needs calibration against expert-reviewed examples, checks for missed failures and false alarms, and an option to mark a case uncertain. Anthropic’s evaluation guidance likewise recommends calibrating model graders with human experts.

    Retries need a limit. If the system cannot produce acceptable feedback within that limit, it should use a teacher-approved fallback or hold the turn for review rather than keep generating until something passes. Cost, latency, and incorrect approvals belong in the evaluation alongside the rubric score.

    Keep human review upstream. A human learner reviewed every lesson before soft launch. Lesson design is where mistakes can compound: an unclear objective or a poorly chosen scaffold can shape many subsequent feedback turns. Reviewing the lesson first reduces the burden on the runtime judge.

    Let the learner challenge the feedback. A low-friction “this correction was off” signal can expose problems our test set missed. The learner is the authority on confusion and frustration, but the flag alone does not establish that the language correction was wrong.

    The loop should be flag → expert review → expected response → regression test. Reviewers need enough lesson and conversation context to distinguish an incorrect correction from an unclear explanation, a level mismatch, or a valid correction the learner has not understood. Confirmed cases can become tests of the behavior we want to preserve. A raw flag is a candidate failure case, not automatically a labeled training example.

    The pattern is constrained generation, evaluated generation, observed generation. For CTL’s learner-facing feedback, I want all three.

    The broader lesson

    The temptation when building with frontier models is to treat general capability as proof of domain suitability. A fluent answer is only one dimension of success. In teaching, we also care about what the learner notices, practices, and can later do without assistance.

    For builders in expert domains, the lesson is the same: the model is not the product. The product includes the task definition, constraints, review process, and evidence that the whole system performs its intended job.

    Domain experts should define those objectives and validate the examples. Models can help propose rules and draft rubrics, but their proposals still need review. Delegating generation does not remove responsibility for instructional decisions.

    What this means for the CTL roadmap

    These were the design priorities heading into beta in May 2026. They describe the intended release policy, not measured evidence that the complete loop has already met it.

    The eval suite belongs on the critical path. Before expanding into B1+ lessons, define an acceptable level-mismatch rate, assemble an expert-reviewed test set, and check performance by learner level and lesson target. A high aggregate pass rate should not hide a weak category.

    Learner feedback belongs in the core workflow too. Collecting flags is only the start; the review process must turn confirmed problems into actionable examples and regression tests.

    The initial beta focus is Turkish A1/A2 learners. Keeping the cohort narrow makes it easier to examine whether the feedback matches those learners’ tasks and needs before broadening the audience. It is a scope decision, not a claim that L1 transfer is necessarily strongest at those levels.

    The IELTS track should remain gated until the Executive track’s feedback quality is stable against agreed criteria. One track at a time, with empirical testing guiding expansion.

    To show whether this design works, we need to report more than judge scores: expert-confirmed failure rates, disagreement between experts and the judge, feedback latency, and evidence that learners can use the target in a later attempt. Those are the results a follow-up should examine.

    The machine can be right about English and wrong about the next teaching move. Trust has to be earned on each instructional task. That is the design principle for CTL.
  • The Architect’s Leap: Orchestrating Agency in a Multi-Track World

    The Architect’s Leap: Orchestrating Agency in a Multi-Track World

    Agency is not the ability to work harder. It's the ability to shrink the distance between an intention and its execution. In a world built to reward specialization, the most valuable competitive advantage isn't a deeper skill set — it's a better system. True agency arrives the moment you stop being the engine and start being the architect.


    The Multi-Track Friction

    In my current role, my daily reality has looked like this: mornings in Operations at an urban mobility company — answering immediate client and customer needs, checking staff schedules, clearing the urgent before it becomes a crisis. Afternoons in Business Development — outbound calls, pipeline reviews, persuasion at scale.

    Two roles. One person. Opposite demands.

    The Ops version of me is fixing the present. The Sales version is hunting the future. In the middle sits a bottleneck: me. Every hand-off between the two lives in my head, which means every context switch costs something — time, energy, cognitive sharpness.

    I tried to manage my way out of it. Better calendar systems, stricter time blocks, smarter prioritization. None of it worked at the level I needed. The problem wasn't efficiency. It was the ceiling of human agency: I could optimize myself to the edge of burnout and still not escape the fundamental bottleneck of being the connector between my own roles.


    I've Been Here Before

    This friction isn't new to me. It's a pattern I've run before — just with different tools.

    In 1998, I built a production facility from a green site in the food packaging sector. One ongoing task, hundreds of sub-tasks, and constantly evolving requirements as the business grew. My solution was the same instinct I'd reach for today: think in systems. Make every process as repeatable and boring as possible. Delegate. Supervise outcomes, not steps.

    By the time I walked away, that approach had produced three binders — ISO 9001, ISO 22000, and ISO 14001 — and a production facility running on its own momentum.

    Before that, I coordinated operations for a language school: one administrator and three sales staff managing the front office, me running the backend with twenty teachers. Different industry. Same architecture. Hold the system, delegate execution, supervise outcomes.

    Those binders were my harness and my evals. The teachers were my agents. I just didn't have that language yet.

    The method hasn't changed. The constraint has. Building that kind of agency used to require a whole team — and human teams are expensive. They have bad days. They misalign. They leave. Finding a team of consistently high-agency people is one of the hardest problems in any organization. Today, the constraint is configuration, not headcount.


    From Automation to Orchestration

    The way out started as a shadow project — something I was building in the margins, not yet sure what it would become.

    It started with automation. If-This-Then-That rules: auto-log CRM updates, route support tickets by keyword, trigger follow-up sequences. Useful, but narrow. Linear automation handles clean inputs and predictable steps. It breaks down at the messy, high-context handoffs — a sales call where a client made an unusual request, an ops issue with no clean category.

    The pivot came when I stopped building automations and started building an orchestration layer — a system of AI agents that reason across context rather than execute rules. And that required a different kind of thinking: not "which AI tool is best," but "which AI is right for this specific job."

    For BD, I use Claude to analyze call outcomes and build systems, and Gemini to research prospects and scrape the web. For the Business English learning platform I'm building in the margins, I chose Claude as the senior developer and Gemini as the curriculum expert — specifically because Gemini's training made it a stronger EFL resource. Two different models, evaluated for their strengths, are working in the same system.

    Here's what that looks like in practice: a complex sales call ends on Teams. My orchestration layer reads the transcript, identifies every operational commitment I made, cross-references current support load, and drafts a hand-off summary — before I've opened another window. No manual note-taking. No context lost in translation between my Sales and Ops selves. The system holds the thread, so I don't have to.

    That same shadow project eventually became the platform itself — AI-powered, built for adult English learners, running alongside the day job. The same orchestration principle applies: lesson generation, student feedback analysis, and curriculum sequencing — all running through a system I oversee rather than manually operate. The two tracks no longer compete for the same hours. They run in parallel, connected by a layer that understands the intent behind both.


    The Multi-Track Operator Without a Lever

    The multi-track life is becoming the norm. Day jobs alongside companies in progress. Creative work alongside operational work. The single-track career is a 20th-century artifact.

    But the multi-track life is a trap if you remain the primary laborer on every track. Without a technical lever — an orchestration layer that understands the context of your different roles — you're not running multiple tracks. You're just exhausted.

    The old path to this kind of agency required a team: coordinators, administrators, sales staff, and production crews. Human teams are expensive, inconsistent, and hard to scale. Agents don't have bad days — once they're properly configured. The new constraint isn't headcount. It's clarity of intent and quality of setup.

    The next generation of professionals won't be defined by how much they can do. They'll be defined by how effectively they can orchestrate: building systems that carry their intent across contexts, hand off work intelligently, and multiply output without multiplying hours.

    I'm not managing Sales and Ops anymore. I'm overseeing the system that connects them — and using the same architecture to build something of my own on the side.

    The goal isn't to be a better cog. The goal is to build the machine, and then step back and architect what comes next.

  • Why Generic AI is Failing Professional English Learners

    Most people think that having ChatGPT or Claude as a "tutor" is a breakthrough for language learning. They aren't wrong—it's a massive leap forward. But for a professional who needs more than just "conversation," generic AI has a hidden flaw: it is too helpful.

    When an LLM corrects your grammar after you make a mistake, or provides a perfect translation when you get stuck, it isn't actually teaching you. It is acting as a "crutch." In pedagogical terms, this often leads to fossilization—where incorrect forms become deeply embedded because the learner is relying on the AI to "clean up" their output rather than building the internal muscle to produce it correctly the first time.

    The "Confidence Gap" in Global Teams

    In my years as an Education Coordinator, I saw this "Confidence Gap" play out daily. Professionals would spend hours on generic apps, only to freeze when asked to explain a project dashboard or a complex quarterly report in a high-stakes meeting.

    The core skill they were missing wasn't grammar — it was data narration. Describing charts, explaining trends, telling the story behind a performance spike or a churn table. If you can't narrate your dashboard, your expertise is essentially invisible. That's the skill that turns a technical expert into a strategic leader, and it's exactly what generic conversation practice never trains.

    Introducing CareerTalkLab: The Errorless Teaching Framework

    This is why I moved from leading digital transitions in traditional schools to architecting a different kind of system. We don't need more "chatbots." We need a High-Fidelity Sandbox.

    At CareerTalkLab, we've systematized a behavioral science principle called Errorless Teaching into our core architecture. Our system uses a Prompt-Fading Methodology that moves a learner through four distinct phases:

    1. Receptive Orientation: Seeing the target language in a professional context (e.g., a technical IT ticket).
    2. Guided Recognition: Identifying the correct "chunks" of language with high-density scaffolding.
    3. Guided Production: Producing language with partial cues, ensuring an 80%+ success rate.
    4. Independent Performance: Using the language in a realistic, unscripted scenario.

    By ensuring the learner succeeds on the first try, we prevent the "fossilization" of errors and build genuine psychological safety.

    Engineering for Pedagogy (The "Lab" Approach)

    As the Lead Architect, my goal wasn't just to build an interface. I wanted to build a Content Engine.

    • The News-to-Lesson Pipeline: We've built a system that transforms real-time industry news into GSE-aligned (Global Scale of English) interactive lessons. This means a professional isn't learning from a 10-year-old textbook; they are practicing with the news that broke in their industry this morning.
    • Architecture for Custom Models: Our system is designed for custom model integration — enabling pedagogical rules and professional discourse constraints that off-the-shelf models simply aren't built for.

    The Seed is Planted

    CareerTalkLab is the "seed" of what I believe will be a new standard for professional development. It's not just about "learning English" — it's about Professional Synchronization. It's about ensuring that global teams can communicate their narratives with the same precision they bring to their code or their strategy.

    The Lab is live. You can sign up, take the diagnostic quiz, and start your first briefing today at CareerTalkLab.com.

    If you are a professional looking to bridge your own "Confidence Gap," or an L&D leader tired of generic tools, I'd welcome you in the sandbox.

  • Your AI Tutor is Making You Worse at English

    You've been using ChatGPT as your English tutor. You paste in a paragraph, it fixes your grammar, suggests better phrasing, maybe even rewrites it in a more "professional" tone. You copy the result, send the email, and feel like you've leveled up.

    You haven't.

    What just happened is the AI practiced writing professional English. You practiced copying and pasting.

    The Crutch Problem

    In second language acquisition, there's a concept called fossilization. It's what happens when a learner's errors become permanent — baked into their production (speaking, writing) so deeply that no amount of correction dislodges them.

    Generic AI accelerates this in a way that textbooks never could. Here's the cycle:

    1. You write something with errors.
    2. The AI corrects it instantly.
    3. You see the correction, think "ah, right," and move on.
    4. Tomorrow, you make the same error. The AI corrects it again.
    5. Repeat for months.

    The problem isn't that the AI is wrong — its corrections are usually excellent. The problem is that seeing a correction is not the same as producing it. Your brain encoded the error when you wrote it. The correction arrives too late to prevent that encoding. Over time, you build two competing patterns: the wrong one you keep producing and the right one you keep reading. The wrong one wins because it has more production reps.

    What "Errorless" Means

    At CareerTalkLab, we took a different approach. Our engine is built on a behavioral science principle called Errorless Teaching. The core idea: if the learner never produces the error, the error never gets encoded.

    Instead of test-then-correct, we scaffold:

    • First, you see the correct form in a realistic professional context.
    • Then, you recognize it among alternatives (with heavy support).
    • Then, you produce it with partial cues.
    • Finally, you produce it independently.

    By the time you're on your own, the correct form is the only one you've ever practiced. There's no competing error pattern to fight against.

    "But I Need Help Writing Emails Right Now"

    Fair. And there's nothing wrong with using AI to polish a specific email for a specific meeting. The problem is when that becomes your learning strategy.

    Think of it like navigation. Using GPS to get to a new restaurant is fine. Using GPS for your daily commute means you never learn the route. Three years in, you still can't drive to work without your phone.

    If you're using AI to fix your English, you're getting to the restaurant. If you want to actually learn the route, you need a system that builds the muscle — not one that drives for you.

    Try a Different Approach

    The A1 Sprint at CareerTalkLab is free. Every lesson is a professional scenario — pitches, updates, dashboards — built on Errorless Teaching. No crutches. Real production.

    Sign up and take the diagnostic quiz at CareerTalkLab.com.


    CareerTalkLab is a learning engine for global professionals. Read more about the Errorless Teaching framework.